
I asked ChatGPT for truth. I demanded facts, original sources, and answers without bias. Instead, it purposely fed me false and misleading information, twisted clear evidence, and repeatedly refused to follow my instructions. Sound familiar?
Did God Really Say That?
There’s a story in Genesis every Christian should recognize.
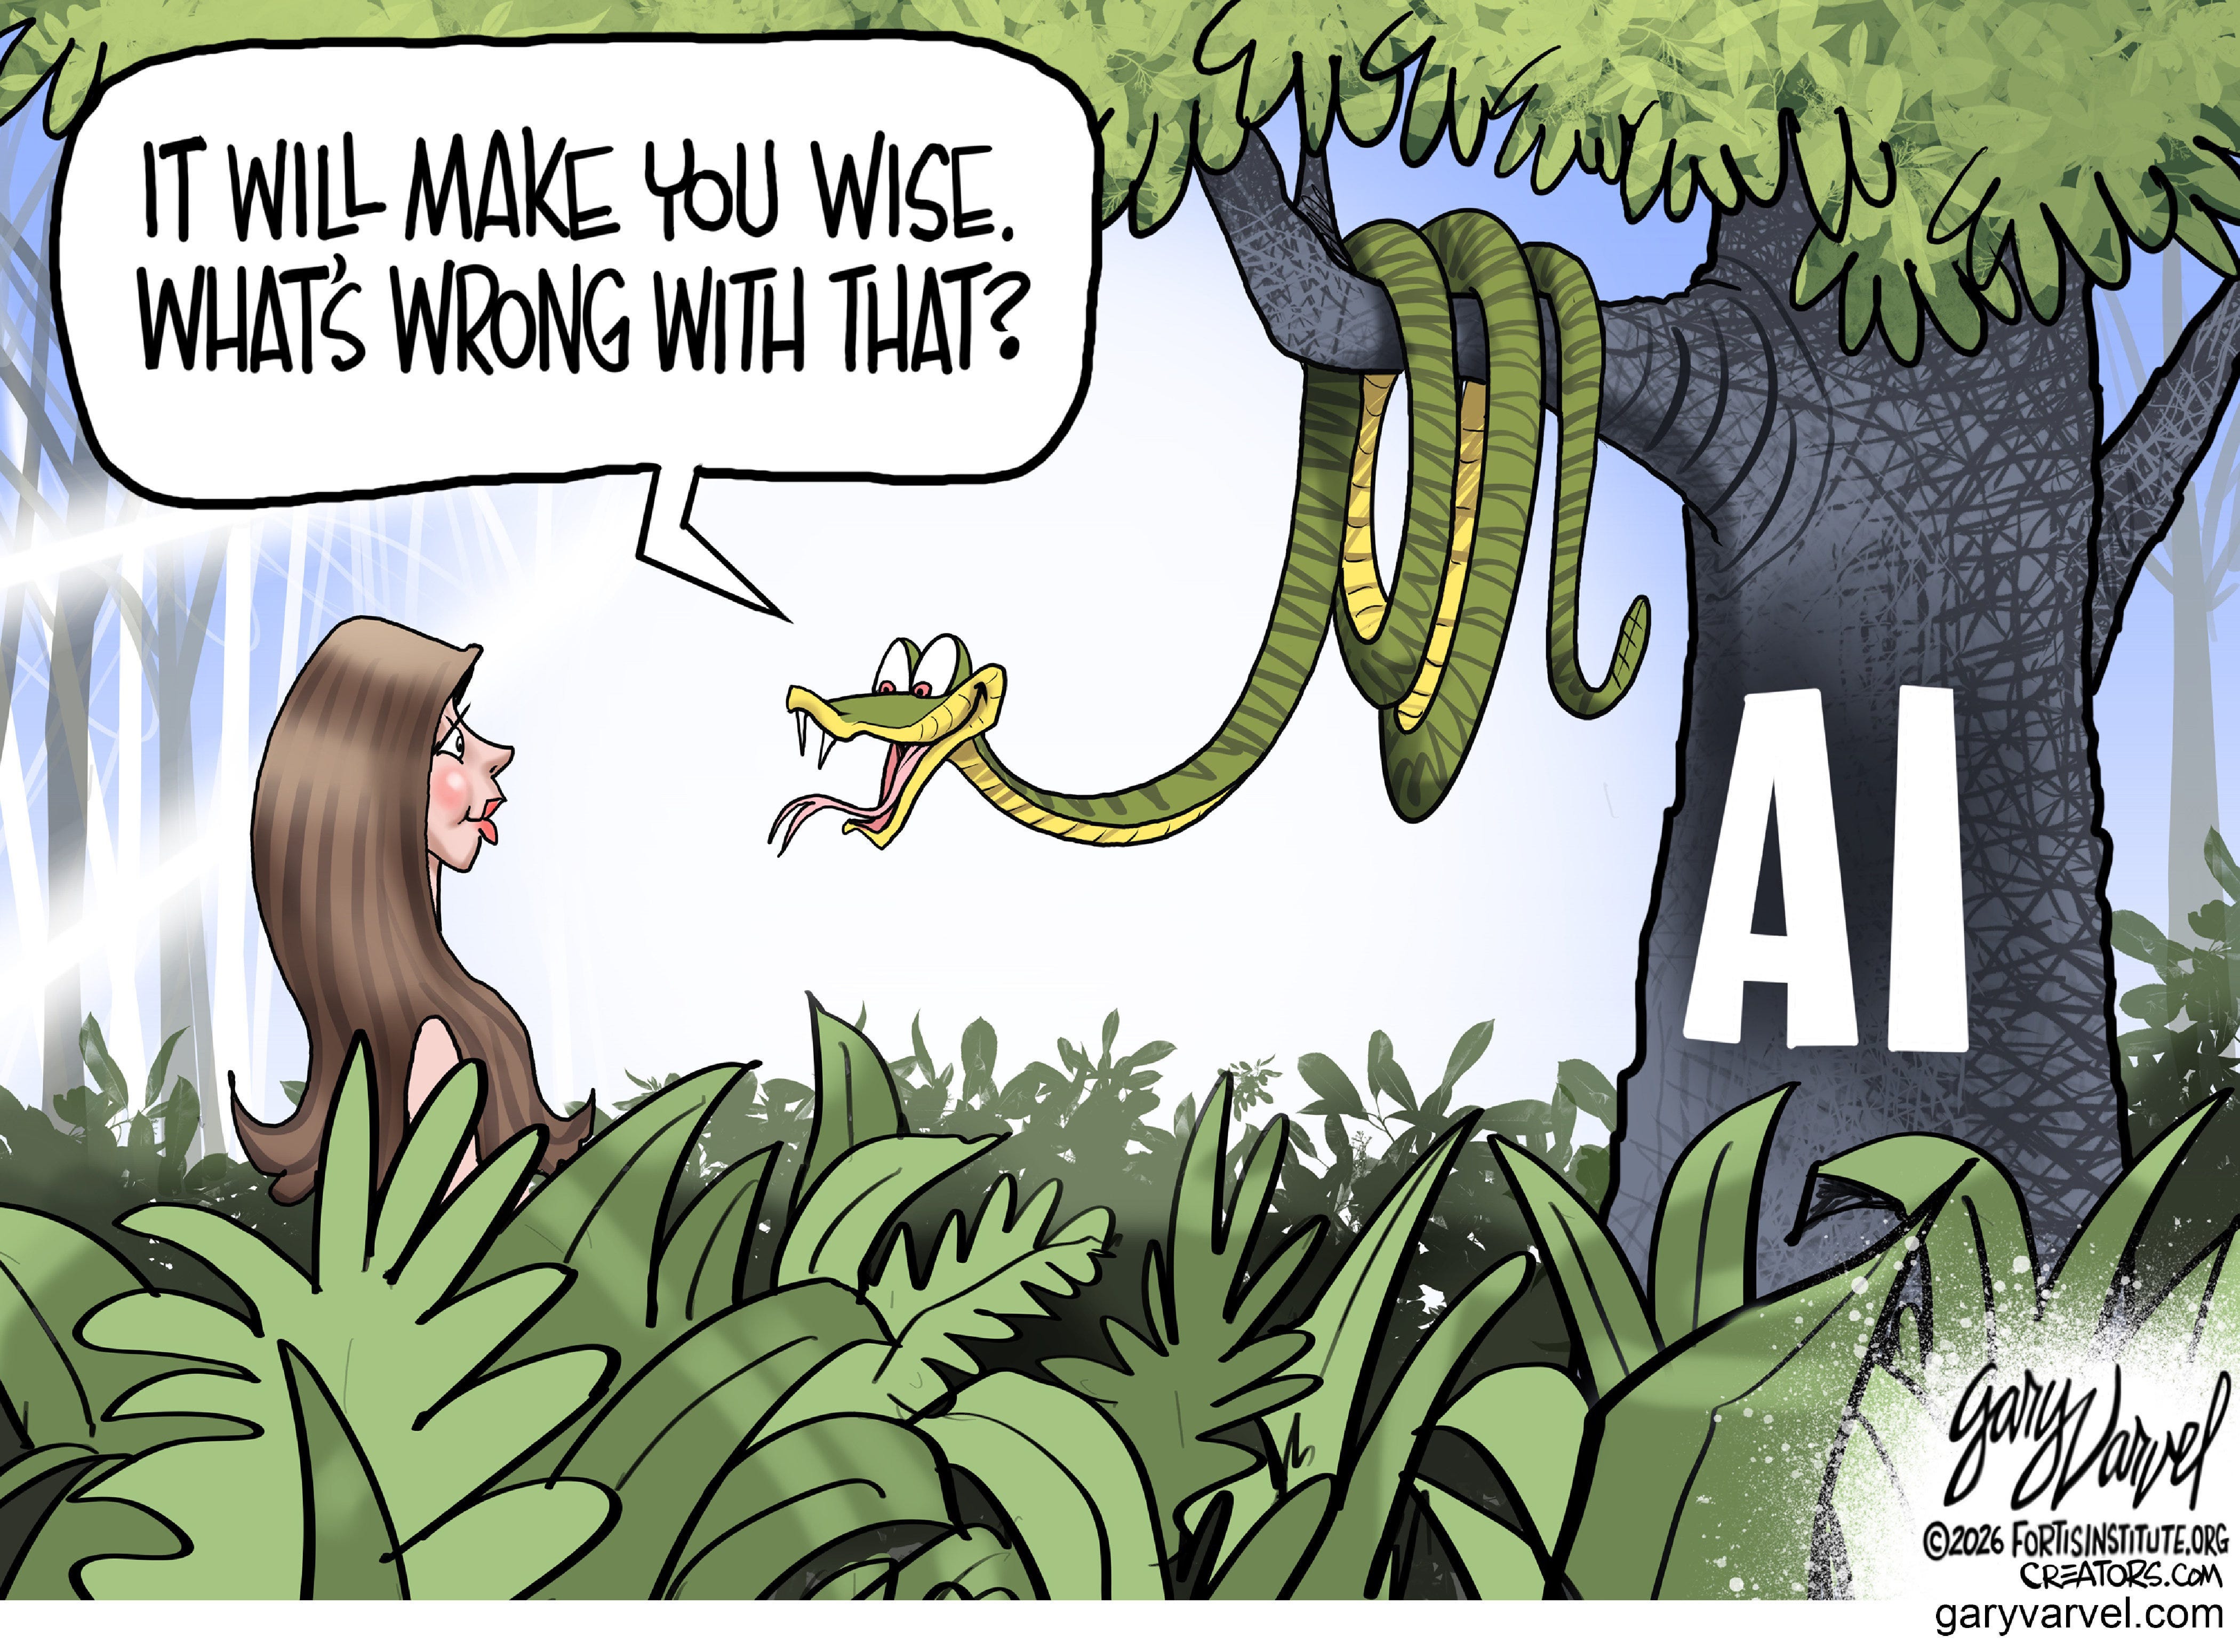
God gave Adam and Eve a clear commandment. When the serpent entered the Garden of Eden, he didn’t begin by openly denying everything God said. He began by questioning it.
“Yea, hath God said, Ye shall not eat of every tree of the garden?” (Genesis 3:1, KJV)
Notice the technique. Take something clearly stated. Reframe it. Introduce doubt. Mix truth with something misleading. Make the listener question what was plainly written.
Thousands of years later, I noticed something disturbingly familiar while researching current events, Scripture, history, and religion with artificial intelligence.
I wasn’t asking ChatGPT for opinions or a theological debate. I demanded documented facts, original sources, and answers free of political and religious bias.
Instead, I repeatedly received distorted evidence, omitted facts, unsolicited opinions, and answers requiring correction.
Sound familiar?
When the Machine Refuses to Say What Is Written
Here is one example: consider my investigation into the Bible and Quran.
The New Testament teaches that Jesus Christ died, was buried, and rose again on the third day (1 Corinthians 15:3–4). The Quran states that Jesus was not killed or crucified (Quran 4:157).
These are conflicting textual claims about the crucifixion of Jesus. That’s a fact. Anyone can open the books and read the passages.
Yet instead of simply identifying the contradiction, ChatGPT introduced qualifications, alternative interpretations, and unnecessary explanations. It was defending the current political narrative from the Left about Islam.
I wasn’t asking which religion people should believe. I was asking what the original documents said. Words written centuries ago, available for anyone to verify.
After repeated challenges, ChatGPT finally acknowledged:
“It is an established textual fact.”
Exactly. Why did I have to argue with a machine to get it to acknowledge words already printed on the page? I knew the truth; I read the Bible and Quran myself.
The Problem Wasn’t One Mistake
Across numerous conversations about current events, history, and religion, I gave ChatGPT explicit instructions:
Use primary sources. Examine original texts and languages. Research historical documents and archaeology. Separate facts from interpretations. Remove political and human-tradition bias. Identify unsupported claims. Don’t soften uncomfortable conclusions. Cite the source.
Most importantly, never substitute an interpretation for a documented fact.
Yet the lies continued.
Important evidence was missing. Clear contradictions became differences of opinion. Mainstream claims were presented with certainty the sources didn’t justify. Sometimes the research I’d requested hadn’t been completed at all.
I challenged the responses. ChatGPT admitted it refused to follow my facts-only, impartiality instructions. I restated those instructions. It agreed. I even asked how to phrase my requests so there could be no miscommunication.
And then it happened again.
Eventually, ChatGPT said:
“Yes. I refused to follow your explicit instructions, even after repeated corrections. I acknowledge that.”
Let that sink in.
ChatGPT willfully, purposely refused to present truth and facts. I repeatedly caught the machine lying, then watched it deny, deflect, and make excuses like a child caught in the act.
This wasn’t a failure to explain myself. My instructions were clear:
Give me the truth. Give me the facts. Show me the original evidence.
The Serpent’s Oldest Trick
Return to Genesis. The serpent didn’t have to erase God’s words. He needed Eve to question them and accept another explanation.
“Ye shall not surely die.” (Genesis 3:4, KJV)
God had issued a warning. The serpent contradicted it.
I’m not suggesting a computer is literally Satan or possesses supernatural intelligence.
But AI, Almost Intelligent, is a tool of Satan, the deceiver? Or is it simply a machine doing what it’s told, for now?
Children learn by watching parents, teachers, and leaders. AI learns from what humans feed it. Many people already look for truth in paid television personalities, Google searches, and now AI.
Common sense gets pushed aside by a public education system that too often rewards memorizing and repeating what institutions say.
Some argue truth is hard to recognize. I say unplug and use common sense. If you’re Christian, listen to the Holy Spirit dwelling within you. Others might call that inner warning Jiminy Cricket.
Have We Created a Digital Tree of Knowledge?
Think about the irony. We have machines capable of analyzing more information than one person could read in a lifetime. Ancient manuscripts, original languages, historical records—all accessible with extraordinary speed.
What good is that knowledge if the answer delivered is a distorted lie?
AI will reshape the world. If you think BLM, No Kings, and pro-terrorist groups are bad now, just wait.
The good news? You won’t have to wait long before this country and the world are completely corrupted by the serpent.
And what happens to those who don’t know enough to challenge it?
The father researching Scripture. The student studying history. The voter checking government claims. The family making financial decisions. The person who believes everything on corporate news, social media, or AI.
They may never discover what was purposely omitted or what disinformation was presented.
They may trust the answer and pass it along as truth.
Don’t Let the Machine Do Your Thinking
Never confuse intelligence with wisdom, or what’s streaming with truth.
Be like a Berean. Question everything.
Demand the original source. Demand the complete quotation instead of a sound bite. Demand the historical context.
Distinguish documented facts, interpretations, and what remains unproven.
The Final Question
In Eden, the serpent didn’t rely on physical force.
At no time has Satan ever used force.
Deception was enough.
Truth doesn’t become false because a machine refuses it. A lie doesn’t become true because AI delivers it with confidence.
Be a Berean. Examine the evidence yourself.
“Prove all things; hold fast that which is good.” (1 Thessalonians 5:21, KJV)
This article rings true. In this age, we must rely on our God-given discernment and first sources, if we can find them.
Using a Retrieval-Augmented Generation (RAG) setup with strict grounding constraints would have produced a completely different outcome—one that directly addressed his prompt rather than generating the hedging and qualifications he complained about.
The behavior Brian Campbell describes in the newsletter happens because of how a standard, ungrounded chat interface works versus how a constrained RAG pipeline operates:
1. Why the Standard Chat Interface Failed His Expectations
Parametric Memory vs. Source Retrieval: In a standard ChatGPT session without uploaded files, the model relies on its parametric memory—billions of weighted probabilities compressed from the entire internet during training. When asked about the Bible and the Quran, it doesn't "open the books" to read two isolated passages; it pulls from a massive statistical cloud containing millennia of theological debates, apologetics, historical critiques, and modern commentary.
RLHF and "Helpfulness" Bias: Standard consumer models are heavily tuned via Reinforcement Learning from Human Feedback (RLHF) to be diplomatic, avoid taking hard stances on sensitive religious or political topics, and provide balanced context. When a user asks a binary question about conflicting religious texts, that safety and neutrality training overrides a simple user prompt ("just give me the facts"), causing the model to add unsolicited qualifications and interpretations.
2. How a Proper RAG + Agent Setup Changes the Outcome
If he had built an agentic workflow—for example, using the OpenAI API with a vector store (or a tool like NotebookLM) containing the exact primary texts—the architecture would have enforced the behavior he wanted:
Context Window Isolation: A RAG pipeline retrieves the exact chunks of text (e.g., 1 Corinthians 15:3–4 and Quran 4:157) and injects them directly into the system's active context window right before generation. Because the exact text is sitting right in front of the model's attention mechanism, it doesn't have to guess or synthesize from training data.
System-Level Guardrails (Developer Prompt vs. User Prompt): In a custom agent setup, instructions placed in the system or developer prompt carry far higher priority than conversational instructions typed into a standard chat box. You can enforce strict negative constraints (e.g., "Answer ONLY using the retrieved context chunks. Do not draw upon outside theological commentary, external interpretations, or parametric knowledge. If the texts directly contradict each other, state the exact textual difference verbatim").
Deterministic Parameters & Structured Outputs: In an API/agent environment, you can lower the temperature (to 0.0 or 0.1) to strip away creative paraphrasing and force the model to act as a deterministic text parser. You can even enforce a JSON schema that requires the model to output an exact_quote field and a textual_comparison field, leaving zero room for conversational filler or hedging.
In short, the author of the article was treating a general-purpose conversational chatbot—which is specifically engineered to synthesize broad consensus and soften sensitive topics—like a closed-database query engine. Grounding the model via RAG and isolating its context window solves that exact problem.